Transcription that stays on your machine
The Hapa Podcast Transcriber is a desktop application I built to solve a simple problem. I needed accurate transcripts of my podcast episodes without paying for a cloud service every month or sending my audio files to someone else’s server.
It uses OpenAI Whisper, an open-source speech recognition model, and runs it entirely on your computer. After the one-time setup, it works offline. Your audio never leaves your machine.
The app connects to the internet for one other reason. When it starts, and when you click Check for Updates, it checks hapamedia.com for a newer version and shows a notice if one is available. That request sends only the app’s name and version number.
It also supports speaker diarization, which means it can tell voices apart and label who said what. That makes it a good fit for interview podcasts.
Private
Your audio files never leave your computer. No uploads, no cloud processing, no data collection.
Free
No subscriptions, no API keys to pay for, no usage limits. Download once and use it as much as you want.
Speaker Labels
Identifies different voices and labels them in the transcript. Built for interviews.
All Formats
Outputs TXT, SRT, VTT, JSON, and Podcasting 2.0 JSON, ready to reference from your RSS feed.
GPU Accelerated
Detects and uses an NVIDIA, AMD, or Apple Silicon GPU for faster transcription.
Cross-Platform
One download works on Windows, macOS, and Linux, with an installer and uninstaller for each.
Simple from start to transcript
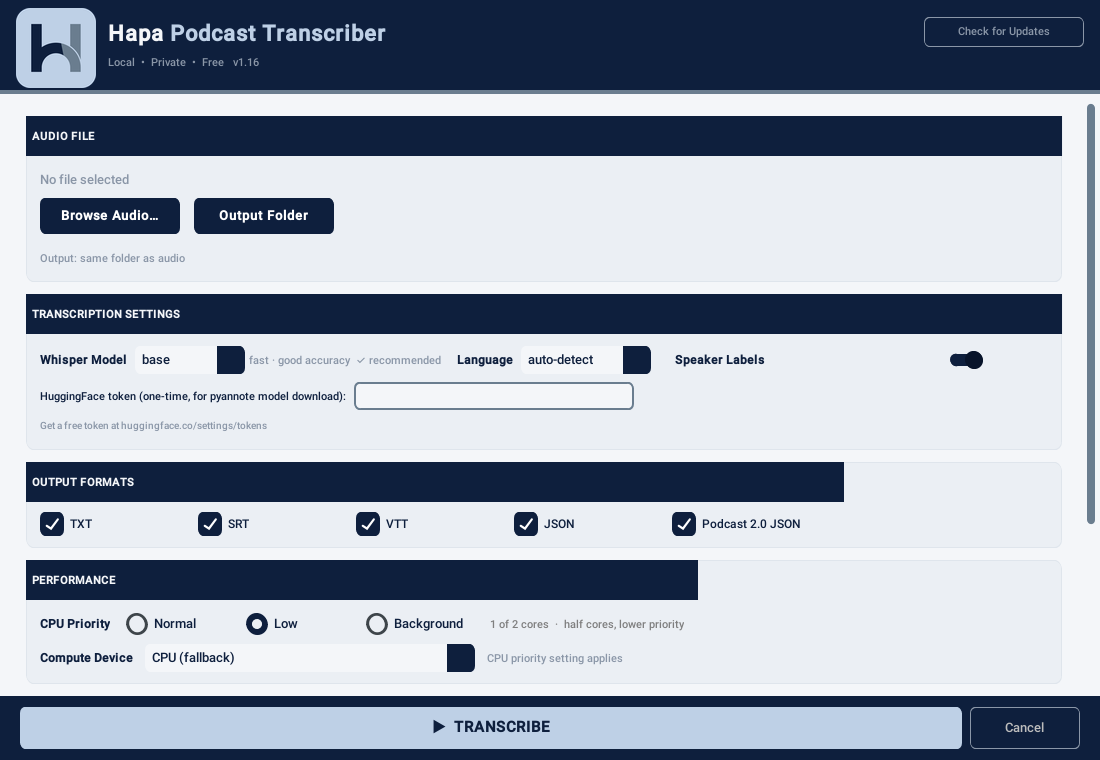
The Hapa Podcast Transcriber window
Download and install
Download the zip, extract it, and run the installer for your operating system. It sets up a Python environment, installs Whisper and the other dependencies, and downloads the Whisper base model (about 150 MB) one time.
Open the app
Launch Hapa Podcast Transcriber from your desktop icon, Start Menu, Applications folder, or application launcher.
Choose your audio
Browse for your MP3, WAV, M4A, FLAC, OGG, AAC, OPUS, WMA, or MP4 file. Pick an output folder, or let the app save transcripts next to the original audio. The file dialogs open in the folders you used last time.
Set your options
Pick a Whisper model, choose a language or auto-detect, turn speaker labels on or off, choose output formats, and set CPU priority so transcription can run quietly in the background.
Click Transcribe
Press Transcribe and follow the progress log. If transcript files with the same names already exist in the output folder, the app asks before replacing them. Click Cancel to stop a run partway through. When it finishes, your transcript files are in the output folder.
Every format podcasters need
The app writes all of your transcript files in a single pass. Choose the ones you want, or keep all five.
| Format | File | Best For |
|---|---|---|
| TXT | .txt | Plain readable transcript for your website, show notes, or reference |
| SRT | .srt | Subtitles for video versions of your podcast, YouTube, or video editors |
| VTT | .vtt | WebVTT captions for HTML5 and web-based podcast players |
| JSON | .json | Full timestamped segment data for developers or custom integrations |
| Podcast 2.0 | _podcast20.json | The <podcast:transcript> tag in your RSS feed |
Podcasting 2.0 ready: The Podcast 2.0 JSON file follows the official podcast namespace transcript spec. Upload it to your server and point to it from your RSS feed. The Hapa RSS Feed Builder can add the tag for you, and the Hapa Chapter Creator can turn the transcript into chapters.
Pick your speed and accuracy
Whisper comes in five sizes. The app defaults to base, which balances speed and accuracy well for most podcasts. You can switch to a larger model any time for more accurate results on difficult audio.
| Model | Size | Speed (1 hr audio, CPU) | Accuracy |
|---|---|---|---|
| tiny | 75 MB | ~5 min | Good |
| base ★ | 145 MB | ~10 min | Very good (default) |
| small | 465 MB | ~20 min | Great |
| medium | 1.5 GB | ~45 min | Excellent |
| large | 2.9 GB | ~90 min | Best |
Have a GPU? The app detects NVIDIA (CUDA), AMD (ROCm), and Apple Silicon (Metal) GPUs and uses them automatically. A GPU can run 5 to 10 times faster than a CPU. Times above are approximate for a modern laptop CPU.
Know who said what
Speaker diarization detects different voices and labels them in the transcript, so you get a readable conversation instead of a wall of text:
[SPEAKER_01] Thanks for having me. I’ve been looking for something like this for a while.
[SPEAKER_00] Let’s start with why transcripts matter for podcasters.
Speaker labeling uses pyannote.audio and needs a free HuggingFace account and access token. Setup takes a few minutes and only happens once. You can also switch speaker labels off for faster transcription without them.
It works best with two distinct voices and little crosstalk. Heavy background music, frequent interruptions, or more than four speakers reduce its accuracy.
What you need to run it
Python 3.10+
On Windows and macOS, install it first from python.org. On Windows, check “Add Python to PATH.” The Linux installer installs Python and python3-venv for you.
ffmpeg
Required for audio processing. The installer downloads it on Windows, installs it with your package manager on Linux, and installs it with Homebrew on macOS when Homebrew is present.
~500 MB Disk
Covers the base Whisper model and the Python environment. Larger models need up to 3 GB more.
4 GB RAM
8 GB or more recommended. Larger Whisper models need more memory.
Linux: python3-venv on Ubuntu, Mint and Debian. These distributions leave out Python’s virtual environment module, and the app can’t install without it. The Linux installer checks for it and installs it with apt. If it can’t, for example because it had no way to ask for your password, it stops and prints the exact command to run. On Ubuntu 24.04 that command is sudo apt install python3-venv python3.12-venv. The version number matches your Python, so copy the command the installer prints, run it, and then run ./install_linux.sh again. Fedora and Arch include the module with Python.